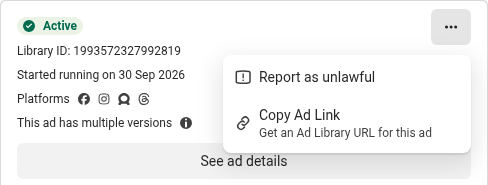
You can't download a video from the Meta Ad Library website: the player and the card menu have no download option. Meta's own Ad Library API returns a link to a rendered ad, not the video file. Our Meta Ads API returns each video as a direct MP4 link, and the script below saves every video from an advertiser.
Why Meta's API doesn't help
Meta's Ad Library API returns ad metadata such as page_id, page_name and ad_snapshot_url, a link that renders the ad in a browser. It has no field for a video or image file. It also covers fewer ads than the website: political and issue ads, and ads delivered to the UK or EU. A US-only ad for leggings is not in it. Our Meta Ad Library API guide covers the access steps.
Get the video URL in one request
We make ToolzerHub. Our Meta Ads API reads the public Ad Library and returns each ad as JSON, including the video links. List a page's ads by its Page ID; each call costs 1 credit:
curl "https://api.toolzerhub.com/v1/meta/page?page_id=129669023798560&country=US&active_status=active" \
  -H "x-api-key: $TOOLZERHUB_API_KEY"
One call returns 10 ads and a cursor for the next 10. One ad, trimmed:
{
  "ad_archive_id": "3508770145952560",
  "page_name": "Gymshark",
  "is_active": true,
  "start_date": 1790838000,
  "publisher_platform": ["FACEBOOK", "INSTAGRAM", "AUDIENCE_NETWORK", "MESSENGER", "THREADS"],
  "snapshot": {
    "display_format": "DCO",
    "body": { "text": "Bestselling, oversized styles for your warm ups & cool downs🎧 👟" },
    "cards": [
      {
        "video_hd_url": "https://video.fsfn3-1.fna.fbcdn.net/o1/v/t2/f2/m366/AQMAsG1J...",
        "video_sd_url": "https://video.fsfn3-1.fna.fbcdn.net/o1/v/t2/f2/m412/AQM2ZMHv...",
        "video_preview_image_url": "https://scontent.fsfn3-1.fna.fbcdn.net/v/t39.35426..."
      }
    ]
  }
}
video_hd_urlis a direct MP4 link; one we fetched came back asvideo/mp4, 9.7 MB. The links are signed CDN URLs, so download soon after the call.- Single-video ads keep the link in
snapshot.videos. Dynamic creative ads (DCO) keep one entry per version insnapshot.cards. Check both.
Don't know the Page ID? GET /v1/meta/search-pages?q=gymshark&country=US returns advertisers with their pageId. Gymshark's is 129669023798560.
Download every video from one advertiser
The script pages through an advertiser's active ads and saves each video version as <ad_archive_id>_<n>.mp4. It skips files it already has, so you can rerun it, and it writes each video to a .part file that is renamed when the download finishes. It needs Python 3 and requests.
import os
import sys
import time

import requests

URL = "https://api.toolzerhub.com/v1/meta/page"
HEADERS = {"x-api-key": os.environ["TOOLZERHUB_API_KEY"]}


def get(params, tries=5):
    # 429 and 503 are retryable; the error body says how long to wait.
    for attempt in range(tries):
        r = requests.get(URL, headers=HEADERS, params=params, timeout=90)
        if r.status_code not in (429, 503) or attempt == tries - 1:
            r.raise_for_status()
            return r.json()["data"]
        wait = r.json().get("error", {}).get("details", {}).get("retryAfter", 5 * (attempt + 1))
        time.sleep(min(wait, 60))


def page_ads(page_id, country, max_pages):
    cursor = None
    for _ in range(max_pages):
        params = {"page_id": page_id, "country": country, "active_status": "active"}
        if cursor:
            params["cursor"] = cursor
        data = get(params)
        yield from data["items"]
        if not data["pageInfo"]["hasNextPage"]:
            break
        cursor = data["pageInfo"]["cursor"]


def video_urls(ad):
    # Single-video ads use snapshot.videos; dynamic creative ads put each version in snapshot.cards.
    snapshot = ad["snapshot"]
    for media in (snapshot.get("videos") or []) + (snapshot.get("cards") or []):
        url = media.get("video_hd_url") or media.get("video_sd_url")
        if url:
            yield url


def download(url, path):
    # Write to .part and rename when complete, so a broken download is fetched again next run.
    part = path + ".part"
    with requests.get(url, stream=True, timeout=120) as r:
        r.raise_for_status()
        with open(part, "wb") as f:
            for chunk in r.iter_content(1 << 16):
                f.write(chunk)
    os.replace(part, path)


def main(page_id, country="US", max_pages=3, out="videos"):
    os.makedirs(out, exist_ok=True)
    ads = saved = 0
    for ad in page_ads(page_id, country, int(max_pages)):
        ads += 1
        for n, url in enumerate(video_urls(ad), 1):
            path = os.path.join(out, f"{ad['ad_archive_id']}_{n}.mp4")
            if not os.path.exists(path):
                download(url, path)
                saved += 1
    print(f"{ads} ads checked, {saved} new videos saved to {out}/")


if __name__ == "__main__":
    main(*sys.argv[1:])
Run it with the Page ID, country and how many pages of 10 ads to read:
export TOOLZERHUB_API_KEY=your_key
python download_ad_videos.py 129669023798560 US 2
country decides which ads you see, the same as the country picker on the website, so run the script once per market. To search by keyword instead of by advertiser, use /v1/meta/search?q=...; the response has the same shape.
What came out
That run printed 20 ads checked, 9 new videos saved to videos/ after 20 seconds and wrote 48 MB. 5 of Gymshark's 20 active US ads carried video: 4 dynamic creative ads with two versions each, and 1 plain video ad. The other 15 were 6 catalog ads (DPA), 8 dynamic creative ads without video and 1 image ad. Catalog ads carry product images, not video.
What it costs
Each call costs 1 credit and returns 10 ads. Add page_size=50 and the same credit returns 50, in 11 to 16 seconds against about 3 for 10. So 1,000 ads cost 100 credits at the default or 20 at page_size=50, and the Gymshark run was 2 credits. Downloading the MP4 itself is not an API call and costs nothing.
You get 100 free credits a month; $19 buys 10,000 credits that never expire, and plans for higher volume cover more advertisers. Set your key and the first advertiser's videos are on disk in under a minute.
To pull the ad text, dates and platforms into a spreadsheet instead of video files, see the Facebook Ad Library API with Python. For TikTok ads, the TikTok Ad Library API guide has a script that saves a brand's videos.
We are not affiliated with Meta.