You can open any public Threads profile in a browser without an account, but Threads stops you after a few posts. We opened five big accounts in a logged-out browser, and each showed 3 to 6 of its posts before a "Log in to see more" banner. Our free Threads profile viewer shows a profile and its latest 5 posts, and the API below reads the whole feed.
What Threads shows logged out
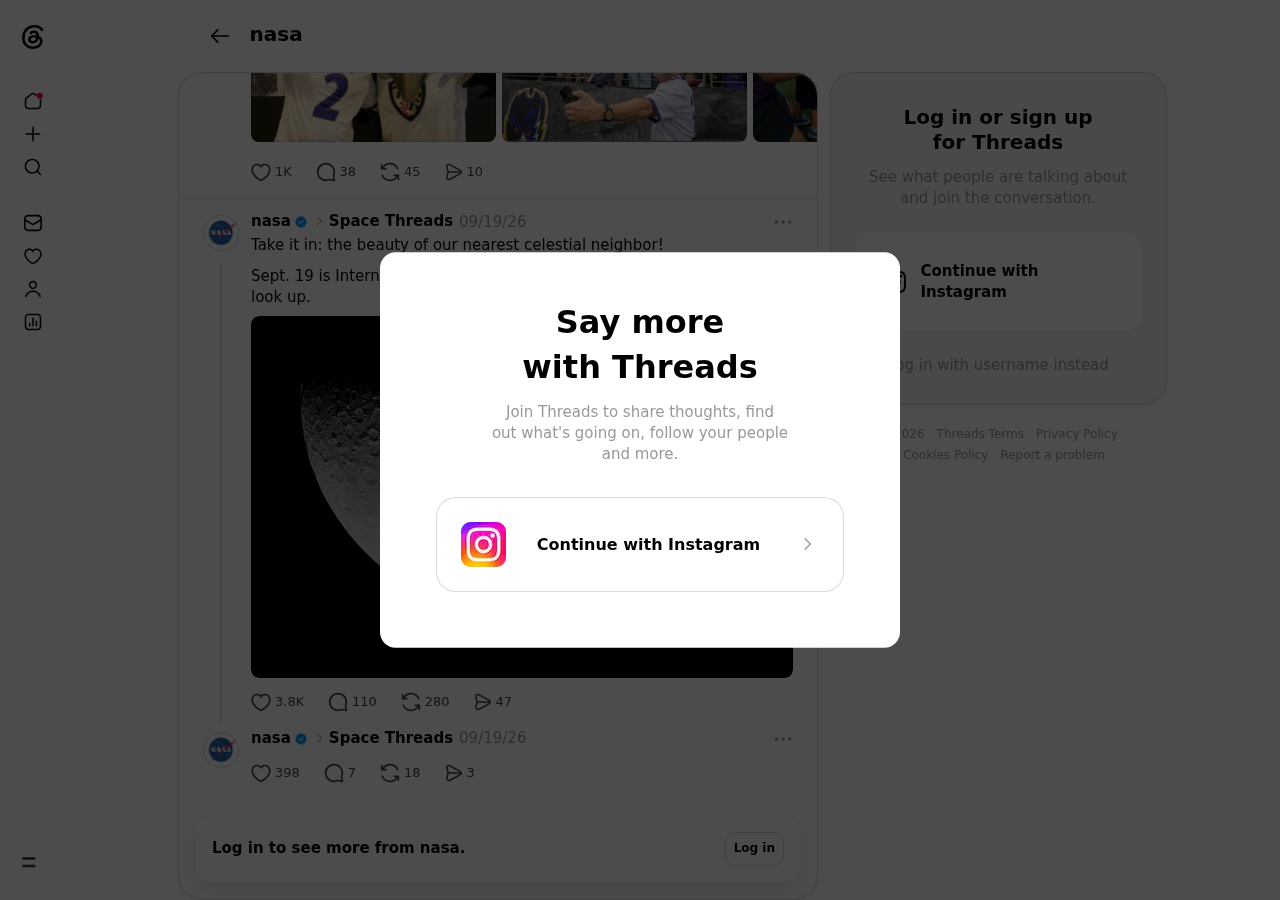
Type threads.com/@username into a browser and the profile loads: name, bio, follower count and the top of the feed. Scroll and a "Say more with Threads" window asks you to continue with Instagram. Closing it doesn't load more posts, and the Replies tab sits behind the same window.
| Profile | Posts shown logged out |
|---|---|
| zuck | 6 |
| natgeo | 5 |
| nasa | 4 |
| nike | 4 |
| mosseri | 3 |
Does Threads show who viewed your profile?
Not by name. On your own post, View activity lists who liked, reposted and quoted it, while views appear only as a number. Nothing on that help page names a person who only looked, at a post or at a profile.
What Meta's Threads API is for
Meta's Threads API is built for apps that post and read on behalf of the account that logged in. Its profile lookup for other accounts works on standard access only for some official Meta accounts, such as @threads; anyone else needs Meta's App Review. Our Threads API guide covers those limits.
Read a whole profile with ToolzerHub
We make ToolzerHub. Our Threads API returns public Threads data as JSON with one API key. Two routes cover a profile:
/v1/threads/profile?username=mosserireturns the bio, follower count and theidthe feed route needs./v1/threads/profile/posts?user_id=<id>returns a page of posts and anend_cursorfor the next one.
curl "https://api.toolzerhub.com/v1/threads/profile?username=mosseri" \
  -H "x-api-key: $TOOLZERHUB_API_KEY"
Each post carries caption.text, like_count, taken_at and reply and repost counts under text_post_app_info.
Save every post to a CSV
The script looks up the profile, follows end_cursor until the feed ends or a page limit, and writes one row per post. It needs Python 3 and requests.
import csv
import os
import sys
import time
from datetime import datetime, timezone

import requests

API = "https://api.toolzerhub.com/v1/threads"
KEY = os.environ.get("TOOLZERHUB_API_KEY")
calls = 0


def cell(value):
    # A leading = + - or @ would run as a formula when the CSV opens in a spreadsheet.
    return "'" + value if isinstance(value, str) and value[:1] in ("=", "+", "-", "@") else value


def get(path, params, tries=4):
    global calls
    calls += 1
    # 429 and 503 are worth a retry; the body says how long to wait.
    for attempt in range(tries):
        r = requests.get(f"{API}/{path}", params=params, headers={"x-api-key": KEY}, timeout=90)
        if r.status_code in (429, 503) and attempt < tries - 1:
            wait = int(((r.json().get("error") or {}).get("details") or {}).get("retryAfter") or r.headers.get("Retry-After") or 5 * (attempt + 1))
            time.sleep(min(wait, 60))
            continue
        r.raise_for_status()
        return r.json()["data"]


def posts(user_id, max_pages):
    cursor = None
    for _ in range(max_pages):
        params = {"user_id": user_id}
        if cursor:
            params["end_cursor"] = cursor
        page = get("profile/posts", params)
        for edge in page["edges"]:
            for item in edge["node"].get("thread_items") or []:
                yield item["post"]
        info = page.get("page_info") or {}
        if not info.get("has_next_page"):
            break
        cursor = info["end_cursor"]


def row(post):
    info = post.get("text_post_app_info") or {}
    return {
        "posted_at": datetime.fromtimestamp(post["taken_at"], timezone.utc).isoformat(),
        "text": cell((post.get("caption") or {}).get("text", "")),
        "likes": post.get("like_count"),
        "replies": info.get("direct_reply_count"),
        "reposts": info.get("repost_count"),
        "url": f"https://www.threads.com/@{post['user']['username']}/post/{post['code']}",
    }


def main(username, max_pages="20", out=None):
    profile = get("profile", {"username": username})
    if not profile:
        sys.exit(f"no public Threads profile for {username}")
    seen, rows = set(), []
    for post in posts(profile["id"], int(max_pages)):
        if post["code"] not in seen and post["user"]["username"] == profile["username"]:
            seen.add(post["code"])
            rows.append(row(post))
    out = out or f"{profile['username']}.csv"
    with open(out, "w", newline="", encoding="utf-8") as f:
        writer = csv.DictWriter(f, fieldnames=list(rows[0]) if rows else ["url"])
        writer.writeheader()
        writer.writerows(rows)
    print(f"{profile['username']}: {profile.get('follower_count')} followers, {len(rows)} posts in {calls} calls, saved to {out}")


if __name__ == "__main__":
    if not KEY or len(sys.argv) < 2:
        sys.exit("usage: TOOLZERHUB_API_KEY=... python threads_posts.py USERNAME [max_pages] [file.csv]")
    main(*sys.argv[1:])
export TOOLZERHUB_API_KEY=your_key
python threads_posts.py mosseri 30
What the two profiles returned
Adam Mosseri's profile, which showed 3 posts logged out, gave 407 posts in 26 calls and 62 seconds. NASA's gave 193 posts in 11 calls and 22 seconds, where the paging stopped. That works out to 16 to 19 posts a page, so one call already shows more than a logged-out visit.
What it costs
Each call is 1 credit: the profile plus one per page of posts, so Mosseri's whole feed cost 26 credits. You get 100 free credits a month; $19 buys 10,000 credits that never expire, and plans for higher volume cover more accounts. Set your key and the first profile is a CSV in about a minute.
To save a post's videos and photos, see how to download Threads videos; for searches and replies, read how to scrape Threads.
We are not affiliated with Meta or Threads.